> ## Documentation Index
> Fetch the complete documentation index at: https://docs.typesafe.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Images
> Send images in a System One request: in the state, inside a question's instructions, and as the criteria a question is judged against.
**Dreamer-ready.** Images and Box questions aren't yet up to our standards to call ready for production, but we're excited for dreamers and builders to play with them. Use them to build prototypes and try ideas. The request format, the answers, and the limits on this page can change between releases, and accuracy will change as we update the models. Tell us what you build, and what breaks, on [Discord](https://discord.gg/typesafe).
To use images or Box questions, send the `TypeSafe-Danger-Zone-Images: true` header with each request that contains an image or a Box question. See [Turning on images](/images#turning-on-images).
An image can go anywhere text can go in a System One request: in the `state`, in a question's `instructions`, and in its `criteria`. Every question type accepts images, and the [Box](/primitives/box) question type returns where something is in an image.
 ## Turning on images
Images and [Box](/primitives/box) questions are off by default. To use them, send the `TypeSafe-Danger-Zone-Images: true` header with each request that contains an image or a Box question. The examples under [Uploading images](#uploading-images) show how. The other examples on this page show only the request body.
## Sending images in a request
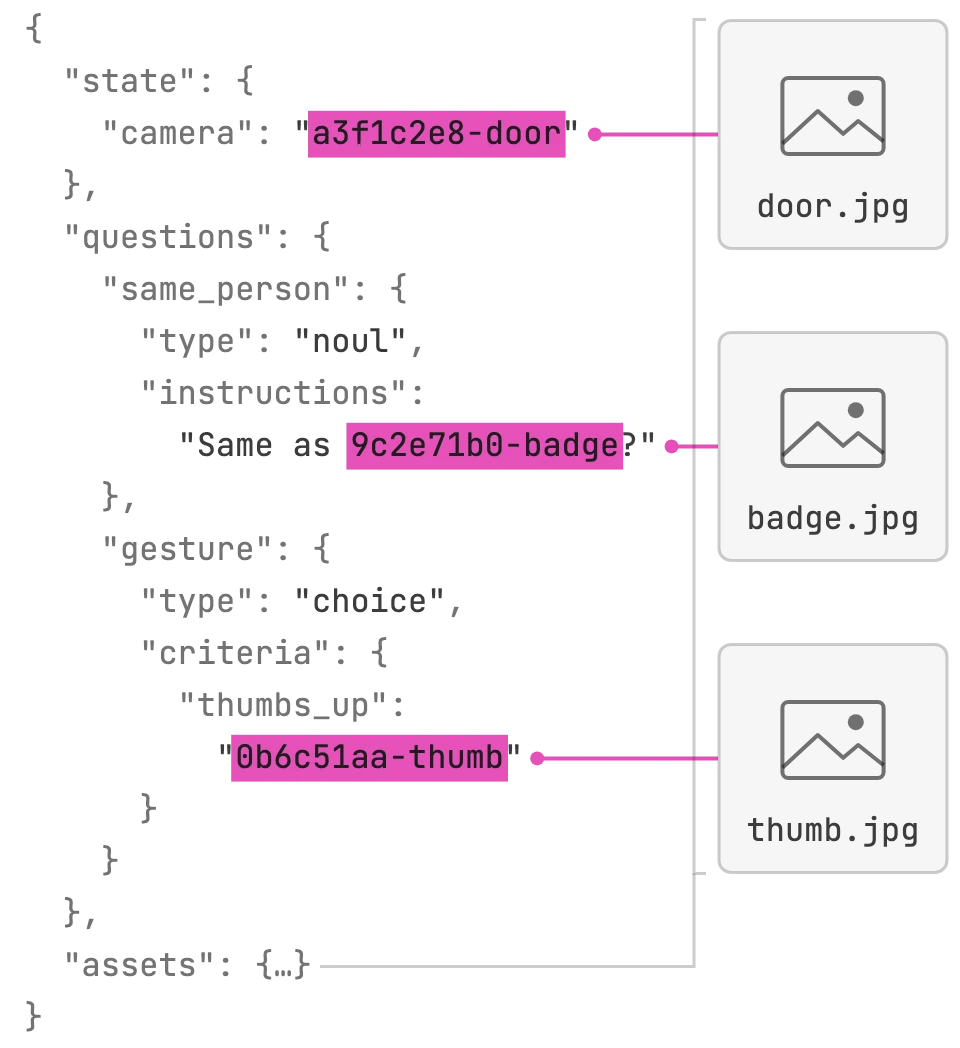
Each image is listed once, in the request's top-level `assets` map. Its key in that map is a reference string. Write the reference wherever the image belongs, as a whole string value or inside a longer string, and the model receives the image in its place.
This request sends a photo of a found dog as the state, and puts the photo from a lost-dog poster directly into one question:
```json theme={null}
{
"model": "jev-latest",
"state": {
"photo": "a3f1c2e8-found"
},
"assets": {
"a3f1c2e8-found": {"type": "image", "format": "jpg", "data_base64": "/9j/4AAQSkZJRg..."},
"77b0d4a1-poster": {"type": "image", "format": "jpg", "data_base64": "/9j/4AAQSkZJRg..."}
},
"questions": {
"same_dog": {
"type": "noul",
"instructions": "Is the dog in `photo` the same dog as in this picture: 77b0d4a1-poster?"
},
"has_collar": {
"type": "noul",
"instructions": "Is the dog in `photo` wearing a collar?"
},
"coat": {
"type": "choice",
"instructions": "What is the coat of the dog in `photo` like?",
"criteria": {
"short": "Short and smooth.",
"long": "Long or feathered.",
"curly": "Curly or wiry."
}
}
}
}
```
Questions can refer to an image in the state by name or path in backticks, the same way they refer to any other field (see [Reference specific fields](/primitives#reference-specific-fields)). An image that only one question uses goes directly in that question's `instructions` or `criteria`, as the poster photo does above.
Jev 1.13 and Jev 1.14 both accept images. [Box](/primitives/box) questions need Jev 1.14.
### Asset fields
The images in the request, keyed by reference string. Every reference must appear somewhere in the `state`, `instructions`, or `criteria`.
The kind of asset. Optional. If you send it, it must be `"image"`.
In a multipart request, the name of the file part that holds the image. See [Uploading images](#uploading-images).
The image file, base64-encoded. Required unless `part` is set. Use the standard base64 alphabet with `=` padding, no line breaks or other whitespace, and no `data:` prefix.
The image's format, in lowercase. Required with `data_base64`. Optional with `part`. `"jpeg"` is another name for `"jpg"`.
Send each image one way, with `part` or `data_base64`. If an asset has both, the API uses `part`.
### References
References are matched as plain text anywhere in the request's strings, so a reference works mid-sentence as well as as a whole value. A short reference such as `cat` could also match inside `category`. Use references that can't occur in your text by accident. A new UUID for each image in each request is the safest choice.
* **Every asset must be referenced.** A request with an asset that is not referenced anywhere returns `400`.
* **Whole values match first.** A string that is exactly a reference becomes that image. In longer strings, references are replaced from left to right, and matches never overlap.
* **Each use adds the image again.** The file is uploaded once, but every place its reference appears adds another copy of the image to what the model reads, and every copy counts toward the [expanded request limit](#limits).
* **Object keys are not replaced.** A Choice option name, a question ID, or any other object key stays text. To define a Choice option with a picture, put the reference in the option's description, as in [Criteria](#criteria).
* **Answers contain the reference, not the image,** wherever they repeat your criteria, such as a Score's `legend`.
* **Keep keys short.** Each reference can be at most 1,024 bytes of UTF-8, and all references in a request together at most 65,536 bytes. These limits count bytes, not characters. A reference can't be empty or only whitespace.
The Python and JavaScript SDKs create references for you. See [Uploading images](#uploading-images).
## Uploading images
With the latest Python or JavaScript SDK, put an image object anywhere text can go. The SDK creates a reference for it and uploads the file. This example sends one doorbell photo as the state and asks two questions about it:
```python Python theme={null}
from pathlib import Path
from typesafe_sdk import Choice, Image, Noul, TypeSafeClient
with TypeSafeClient() as client:
result = client.system_one(
state={"door": Image(Path("door-camera.jpg"))},
questions={
"person_present": Noul(instructions="Is there a person in `door`?"),
"carrying": Choice(
instructions="What is the person in `door` carrying?",
criteria={
"package": "A box or parcel.",
"bag": "A bag of groceries or shopping.",
"nothing": "Empty hands.",
},
),
},
extra_headers={"TypeSafe-Danger-Zone-Images": "true"},
)
print(result.answers)
```
```typescript JavaScript theme={null}
import { openAsBlob } from "node:fs";
import { choice, image, noul, TypeSafeClient } from "@typesafe-ai/sdk";
const client = new TypeSafeClient();
const door = image(await openAsBlob("door-camera.jpg"));
const { answers } = await client.systemOne(
{
state: { door },
questions: {
person_present: noul("Is there a person in `door`?"),
carrying: choice("What is the person in `door` carrying?", {
package: "A box or parcel.",
bag: "A bag of groceries or shopping.",
nothing: "Empty hands.",
}),
},
},
{ headers: { "TypeSafe-Danger-Zone-Images": "true" } },
);
console.log(answers);
```
To put an image inside a sentence, or to choose your own references, see the [SDK guides](/sdk).
### Over HTTP
Without an SDK, send each image as a file part in a `multipart/form-data` request. Multipart is the better choice: it sends the file as it is, while base64 makes each image about a third larger, and that extra size counts toward the 32 MiB [request body limit](#limits). Base64-encode images into the JSON only when you can't send multipart.
Send the JSON body as the first part, named `request`, with content type `application/json`. Send each image as its own file part, and set that image's `part` in `assets` to the file part's name:
```bash theme={null}
curl https://api.typesafe.ai/v1/systemone \
-H "Authorization: Bearer $TYPESAFE_API_KEY" \
-H "TypeSafe-Danger-Zone-Images: true" \
-F 'request={
"model": "jev-latest",
"state": {"door": "a3f1c2e8-door"},
"assets": {"a3f1c2e8-door": {"type": "image", "part": "door-photo"}},
"questions": {
"person_present": {"type": "noul", "instructions": "Is there a person in `door`?"}
}
};type=application/json' \
-F 'door-photo=@door-camera.jpg;type=image/jpeg'
```
The rules for multipart requests:
* The first part is named `request` and holds the JSON body.
* Part names are unique and not empty. `request` is reserved for the JSON body.
* Each image part has content type `image/png`, `image/jpeg`, `image/jpg`, or `application/octet-stream`, or no content type. Any other content type returns `400`.
* Each file part belongs to exactly one asset. A part that no asset names, two assets that name the same part, and an asset whose part is missing all return `400`.
To use the same image in several places, write its reference in each of them.
Base64-encode the file into `data_base64` and set `format`, following the rules in [Asset fields](#asset-fields). Python's `base64.b64encode` produces the right encoding. This Python example sends one photo and asks two questions about it:
```python theme={null}
import base64
import os
import uuid
import requests
def image_asset(path: str) -> tuple[str, dict]:
"""Return a new reference and the asset entry for one image file."""
fmt = "png" if path.lower().endswith(".png") else "jpg"
with open(path, "rb") as f:
data = base64.b64encode(f.read()).decode("ascii")
return str(uuid.uuid4()), {"type": "image", "format": fmt, "data_base64": data}
photo_key, photo = image_asset("door-camera.jpg")
response = requests.post(
"https://api.typesafe.ai/v1/systemone",
headers={
"Authorization": f"Bearer {os.environ['TYPESAFE_API_KEY']}",
"TypeSafe-Danger-Zone-Images": "true",
},
json={
"model": "jev-latest",
"state": {"door": photo_key},
"assets": {photo_key: photo},
"questions": {
"person_present": {
"type": "noul",
"instructions": "Is there a person in `door`?",
},
"carrying": {
"type": "choice",
"instructions": "What is the person in `door` carrying?",
"criteria": {
"package": "A box or parcel.",
"bag": "A bag of groceries or shopping.",
"nothing": "Empty hands.",
},
},
},
},
)
print(response.json()["answers"])
```
## Image placement
### State
Images in the `state` are part of the state, the same as any text or JSON there. The model evaluates them together with the rest of the state, and every question in the request is evaluated against them. A state can mix images with text, and can hold several images, labeled or nested like any other state data. This state holds a short history of camera frames, oldest first:
```json theme={null}
{
"state": {
"frames": [
{"seconds_ago": 2, "frame": "5c0e9a12-f1"},
{"seconds_ago": 1, "frame": "1d7be0c4-f2"},
{"seconds_ago": 0, "frame": "e48a6f30-f3"}
]
}
}
```
A question can ask "Did the door in `frames` open during these frames?" or refer to one frame by path, such as `` `frames[2].frame` ``.
### Instructions
An image in a question's `instructions` is part of that question and is sent only with that question. Put the reference in the sentence where the question needs the image:
```json theme={null}
{
"state": {"door": "e48a6f30-door"},
"questions": {
"is_badge_holder": {
"type": "noul",
"instructions": "Is the person in `door` the same person as in this badge photo: 9a21c7d3-badge?"
}
}
}
```
An image in `instructions` is sent to the model once for every question that includes it. When several questions use the same image, put it in the `state` once and refer to it by path from each question. That uses fewer tokens and less of the [size limits](#limits).
### Criteria
Choice options, Score levels, and Noul `true` and `false` definitions can each include images. This Choice classifies a hand gesture, with each option defined by example pictures. The option names are the values your code receives in `choice`, and the pictures are what the model compares the hand against:
```json theme={null}
{
"state": {"camera": "e48a6f30-cam"},
"questions": {
"gesture": {
"type": "choice",
"instructions": "Which gesture is the hand in `camera` making?",
"criteria": {
"thumbs_up": "0b6c51aa-thumb",
"open_palm": {
"description": "A hand held up with the palm facing the camera.",
"examples": ["4fd2e7b9-palm1", "c83a0e15-palm2"]
},
"fist": "a7e94d02-fist",
"none": "No hand, or a hand that matches none of the examples."
}
}
}
}
```
An option can be an image on its own (`thumbs_up`), a description with one or more examples (`open_palm`), or text only (`none`). The `description` and `examples` keys are names chosen for this example, not required fields: criteria accept any [structure](#structured-data).
Score and Noul criteria take images the same way:
* **Score levels** can each include an example picture. A Score for how open a hand is could use a closed fist, a half-open hand, and an open hand as its three levels.
* **Noul criteria** can define `true` and `false` with pictures: `{"true": {"description": "Correctly assembled", "examples": [""]}, "false": "Parts missing or in the wrong place."}`.
### Structured data
State, instructions, and criteria accept nested JSON [structure](/primitives/advanced), and a reference works at any level of it. A question can refer to one picture in an array as `` `lineup[2]` ``, or to one in a labeled object as `` `faces.happy` ``. A criterion can hold several example pictures as an array.
## Patterns
| Pattern | How it works | Where the image goes |
| - | - | - |
| Compare against a known picture | Ask whether the state shows the same person, product, or place as a known picture. | Known picture in `instructions`, photo in `state` |
| Define options by example | Define each Choice option with one or a few example pictures. | `criteria` |
| What changed | Send the previous frame or a short frame history, and ask about motion, arrivals, or differences. | `state` |
| Look closer when needed | Ask about a small copy of the image first. Send a larger copy (up to the size limit), or a full-resolution crop, only when the answer needs more detail. | `state` |
| Search a large image | Cut the image into tiles and ask a Choice with the tiles as its options. Repeat on the chosen tile until the target takes up most of the tile. | `criteria` |
| Find where it is | Ask a [Box](/primitives/box) question for the edges of the target. | `state`, optionally a picture of the target in `instructions` |
## Limits
| Limit | Value |
| - | - |
| Format | PNG or JPEG, still images only. Animated PNGs are rejected. |
| File size | 16 MiB per image file. For base64, this is the size after decoding. |
| Width and height | 256 to 1568 pixels each. |
| Total pixels (width × height) | 78,400 to 2,458,624, the area of a 280 × 280 to a 1568 × 1568 square. A 256 × 256 image is too small. |
| Request body | 32 MiB, including the JSON, base64 text, and multipart framing. HTTP headers don't count. [Compression](/api#compression) doesn't raise the limit. |
| All images in the request | 32 MiB, shared by every distinct image after the API processes it. Processing re-encodes each image and can make it larger than the file you sent, so a request of small uploads can still go over. |
| Expanded request | 32 MiB for the text, questions, structure, and images after every reference is replaced by its image. Each use of a reference adds the image again: an image that is 10 MiB after processing, referenced four times, is over the limit. |
All limits include both ends of the range. An image outside them is rejected, never resized to fit. If any image in a request is rejected, the whole request fails: there are no partial answers. See [Errors](#errors) for the status codes.
How many images fit in one request depends on these limits and on the [context length](/models). Images have no separate [rate limits](/api#handling-rate-limits): a request with images counts against the same limits as any other request.
To stay under the request limits, send fewer images, send smaller images, put an image that several questions use in the `state` once instead of in each question's `instructions`, or split the work across requests.
## Preparing images
Send each image as a PNG or JPEG, rotated upright and sized within the [limits](#limits). Prepare each one before you send it:
* **Resize before sending.** Scale the image so its longest side is at most 1568 pixels. A typical 12-megapixel phone photo becomes 1568 × 1176. Scale up, or pad, an image smaller than the minimum.
* **Rotate the pixels upright.** The API removes all metadata (EXIF, color profiles, comments) and does not apply the EXIF orientation. A photo that looks upright in your photo viewer can reach the model sideways, so rotate the pixels themselves first.
* **Send a still image.** For an animation or a video, export the frame you want as a PNG or JPEG. Convert other formats, such as GIF, WebP, or HEIC, to PNG or JPEG.
* **Prefer standard JPEG.** A standard 8-bit baseline JPEG is the safest JPEG to send. Re-save progressive JPEGs as baseline.
* **Re-export a rejected file.** If the API rejects a file that opens fine on your computer, open it in a standard image editor or library and export it again as PNG or JPEG.
This Python example uses the Pillow library to prepare one photo:
```python theme={null}
from PIL import Image, ImageOps
with Image.open("photo.jpg") as original:
img = ImageOps.exif_transpose(original) # rotate the pixels upright
img.thumbnail((1568, 1568)) # longest side at most 1568, same aspect ratio
# thumbnail only shrinks: upscale or pad an image under the minimum separately
img.convert("RGB").save("photo-ready.jpg", "JPEG", quality=90) # baseline JPEG
```
## Image tokens
Each image counts as input tokens, billed at the same per-token [input price](/models) as text. There is no separate charge for images. The `usage.input_tokens` field in the response includes the tokens for every image in the request. Image tokens also count toward the request's [context length](/models).
We'll be providing guidance on estimating image token usage soon.
## Errors
| Status | Cause |
| - | - |
| `400` | Images are not turned on: the request has an image or a Box question but no `TypeSafe-Danger-Zone-Images: true` header. See [Turning on images](#turning-on-images). |
| `400` | An image or asset was rejected. The file isn't PNG or JPEG, is damaged or incomplete, or is animated; the image is below the minimum width, height, or total pixels; an asset isn't referenced anywhere; the base64 or `format` is invalid; a reference is empty; or the multipart request breaks a [multipart rule](#over-http). |
| `400` | `max_tokens_exceeded`: the images and text together exceed the request's [context length](/models). Send fewer or smaller images, or move images out of `instructions` into the `state`. |
| `413` | The request is over a size limit: an image file, an image's width, height, or total pixels, the request body, all images together, the expanded request, or the reference lengths. See [Limits](#limits). |
If a request has several problems, the error reports one of them. Check the request against [Limits](#limits) and [Preparing images](#preparing-images).
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.